DOP 337: Nanoseconds Matter - InfluxDB and the Future of Real-Time Data
Show Notes
#337: Time series databases have become essential infrastructure for the physical AI revolution. As automation extends into manufacturing, autonomous vehicles, and robotics, the demand for high-resolution, low-latency data has shifted from milliseconds to nanoseconds. The difference between a general-purpose database and a specialized time series solution is the difference between a minivan and an F1 car - both will get around the track, but only one is built for the demands of real-time operational workloads.
The open source business model continues to evolve in unexpected ways. While companies like Elastic and Redis have seen hyperscalers fork their projects, a new partnership paradigm is emerging. Amazon Web Services now pays to license InfluxDB and offers it as a managed service, signaling a shift toward collaboration rather than competition. This approach benefits everyone: vendors maintain development velocity, cloud providers get workloads on their platforms, and customers receive better-supported products.
Evan Kaplan, CEO of InfluxData, joins Darin and Viktor to discuss the trajectory from observability metrics to physical world instrumentation, why deterministic models matter more than probabilistic ones when your robot might run over your cat, and what it takes to build a sustainable open source company over a decade-plus journey.
Frequently Asked Questions
Why use a time series database instead of PostgreSQL or MySQL?
How long should you keep time series data?
Who does not need a time series database?
Why does physical AI need deterministic models rather than probabilistic ones?
Why has InfluxDB kept a permissive open source license?
Why did AWS partner with InfluxData rather than fork it?
What is the DevOps Paradox podcast?
Episode Transcript
Share and Download
Guests
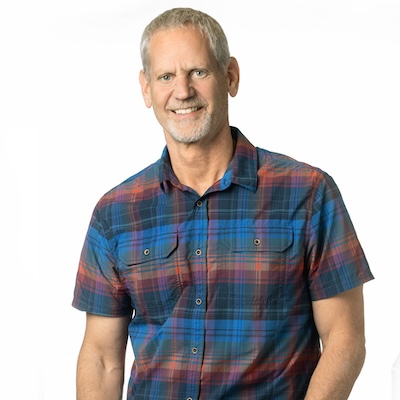
Evan Kaplan
Evan Kaplan is a seasoned entrepreneur and technology leader with over 25 years of executive experience. He is currently the CEO of InfluxData, the company behind InfluxDB, the leading time series database. Since joining InfluxData in 2016, he has played a key role in scaling the company to meet the growing demand for time series data solutions, especially for IoT, Industrial IoT, and AI applications. Previously, Evan served as President and CEO of iPass Corporation, where he led its transformation into a global leader in Wi-Fi connectivity. Earlier in his career, he founded Aventail Corporation, a pioneering SSL VPN company later acquired by Dell, and served as an Executive in Residence at Trinity Ventures.
Beyond technology, Evan is active in philanthropy and venture investing. He is a longtime board member and Treasurer of One Heart Worldwide, a nonprofit that partners with the Nepalese government to improve maternal and neonatal healthcare in remote communities. He also serves on the board of and advises several early-stage AI companies, including Diffblue and Botpress.
An experienced alpinist, Evan is a veteran of multiple Himalayan expeditions, reflecting his passion for adventure and endurance. He holds a Bachelor of Science in Environmental Science from Western Washington University and an MBA from the University of Washington.
Hosts
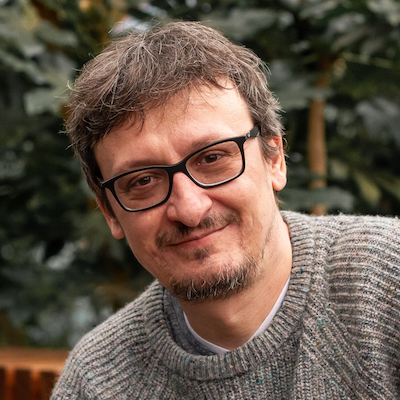
Viktor Farcic
Viktor Farcic is a member of the Google Developer Experts and Docker Captains groups, and published author.
His big passions are DevOps, Containers, Kubernetes, Microservices, Continuous Integration, Delivery and Deployment (CI/CD) and Test-Driven Development (TDD).
He often speaks at community gatherings and conferences.
He has published DevOps Paradox and Test-Driven Java Development.
His random thoughts and tutorials can be found in his blog The DevOps Toolkit.